
We are releasing end-to-end serving support for MOSS-TTS-Local-Transformer-v1.5 on SGLang-Omni. This work was completed jointly by the SGLang-Omni Team and the OpenMOSS Team.
MOSS-TTS-Local-Transformer-v1.5 is an open TTS model that supports 48 kHz stereo audio, zero-shot voice cloning, long-form text synthesis, multilingual generation, duration control, and native streaming. Calling the model with a demo script is not difficult. The real challenge is serving it well: a single request passes through reference audio encoding, the Qwen3-4B autoregressive backbone, a frame-local 12-codebook sampling loop, and a stateful codec decoder.
SGLang-Omni does not force MOSS-TTS-Local-Transformer-v1.5 into a single LLM decode loop. Instead, it serves the model as a three-stage pipeline. This article focuses on that mapping: where the stage boundaries lie, which components require model-specific hooks, and which bottlenecks emerge when the model runs under load.
The MOSS-TTS-Local-Transformer-v1.5 Model
MOSS-TTS-Local-Transformer-v1.5 is the second flagship model in the MOSS-TTS v1.5 family. It follows the Audio Tokenizer + LLM autoregressive approach, using a more capable audio codec and a Global Transformer + Local Transformer generation path.
It supports direct TTS, continuation, zero-shot voice cloning, duration control, explicit pause markup such as [pause 3.2s], and long-form generation of up to 10 minutes. The model covers 31 major languages and was trained on approximately 4 million hours of multilingual speech.

MOSS-TTS-Local-Transformer-v1.5 model architecture
On the audio side, MOSS uses MOSS-Audio-Tokenizer-v2, a neural audio tokenizer with approximately 2B parameters across its encoder and decoder. It operates at 12.5 Hz, supports variable-bitrate compression from 0.125 kbps to 4 kbps, reconstructs 48 kHz stereo audio, and represents speech through residual vector quantization (RVQ).
The generation core uses the Qwen3-4B backbone. The global transformer advances the sequence frame by frame. For each frame, a local transformer first outputs a stop/continue decision, then samples 12 RVQ codebooks in sequence and feeds the current sampling result back before sampling the next codebook.
The token layout visible to the serving layer is [T, 13]: one text/control channel and 12 audio codebook channels. At text positions, channel 0 contains a text token and the remaining channels contain audio padding. At audio positions, channel 0 contains a slot/control token, while each audio codebook channel contains one RVQ code. This is where MOSS first departs from a conventional next-token model: each generated frame is a row rather than a scalar token.
On the public model-level evaluation set:
| Benchmark | WER (lower is better) | SIM (higher is better) |
|---|---|---|
| Seed-TTS-Eval | 5.10% | 69.23% |
| CV3-Eval | 7.48% | 61.59% |
| MiniMax Multilingual | 6.37% | 75.31% |
| X Voice | 20.48% | 63.00% |
These are offline model metrics. The serving benchmarks later in this article use a different evaluation pipeline and should be interpreted as end-to-end system measurements.
MOSS-TTS-Local-Transformer-v1.5 was trained at thousand-GPU scale on Alibaba Cloud’s PPU-ZW810 cluster. This article focuses on the serving side.
Why MOSS Needs a Multi-Stage Serving Runtime
A standard LLM serving engine is built around a repeatedly executed model loop. A single MOSS request contains three different types of work:
- Preprocessing and reference encoding. The text is tokenized, the reference audio is loaded, and the reference waveform is encoded into RVQ codes.
- Autoregressive TTS engine. The Qwen3 backbone and local transformer generate
[1, 13]frame rows. - Streaming vocoder. The generated RVQ rows are decoded into waveform chunks by the stateful MOSS codec decoder.
Each stage has different bottlenecks. Reference encoding runs a large neural codec encoder. AR generation combines ordinary backbone decoding with a very small but strictly serial local codebook loop. The vocoder is a stateful decoder that must retain streaming state across chunks. The system must manage all three components simultaneously while preventing batching or memory behavior in one stage from disrupting the others.
Serving MOSS with SGLang-Omni
SGLang-Omni serves MOSS-TTS Local Transformer v1.5 as a three-stage pipeline:
preprocessing -> tts_engine -> vocoder
The preprocessing stage parses OpenAI-compatible requests, prepares the multi-channel prompt, and encodes reference audio for voice cloning. The tts_engine stage runs on OmniScheduler, allowing MOSS to reuse SGLang’s request batching and KV-cache mechanisms while carrying model-specific [T, 13] rows. The vocoder stage consumes the generated rows in streaming mode and returns audio chunks from a persistent codec streaming session.
The reused components are the runtime structure: stage lifecycle, scheduler interface, inter-stage routing, streaming outputs, process placement, and stage-level resource accounting. The MOSS-specific components are smaller and more explicit: how to construct the multi-channel prompt, how to run the frame-local codebook loop, and how to connect the MOSS codec as a streaming decoder. The next section focuses only on these MOSS-specific bottlenecks and optimizations.
End-to-End MOSS Optimizations
After the pipeline was functional, we optimized the stages where profiling repeatedly revealed redundant work or launch overhead.
| Area | Change | Main Benefit | Source |
|---|---|---|---|
| Model serving baseline | MOSS Local model, pipeline, and API support | Establishes the three-stage serving path | PR #728 |
| Reference encoding | Batched encoding, content-addressed LRU cache, and single-flight deduplication | Avoids repeatedly running the codec encoder for reused speakers | PR #748PR #778PR #788 |
| AR engine | Decode-state pool, frame CUDA Graph support, and GPU-native row hash | Keeps decode state at stable GPU addresses and removes per-frame host hashing | PR #745 |
| AR engine | Frame launch-state pooling and async decode plumbing | Reduces launch preparation overhead and fixes decode-step ownership issues | PR #759PR #758 |
| AR engine | Compiled seeded sampler | Fuses the hot sampling path while preserving deterministic per-request sampling | PR #773 |
| Vocoder | Stateful streaming session, stream slots, and coalesced chunk scheduling | Supports frame-level audio streaming with request isolation | PR #753 |
| Vocoder | Stateful vocoder CUDA Graph | Accelerates short streaming decode steps | PR #798 |
| Cross-stage | Explicit colocated memory budgeting | Prevents codec and AR memory pressure from interfering with each other | PR #810 |
The Source column lists SGLang-Omni GitHub PR numbers. Click to view the details.
Reference Audio Encoding
Voice cloning often reuses the same group of speakers across many prompts. This is important for MOSS because reference encoding runs a large codec encoder before AR generation begins.
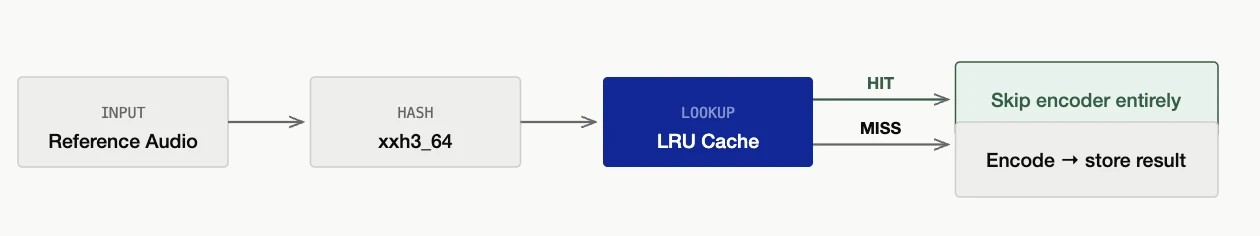
Content-addressed reference audio cache
SGLang-Omni combines batched reference encoding with a content-addressed LRU cache. Repeated references use audio content rather than file paths as the key, so copied or renamed files can still reuse the same encoded RVQ result. The single-flight path merges concurrent misses for the same speaker and avoids launching duplicate codec encodes during cold-cache bursts.
On the SeedTTS English evaluation, with 2x H100 GPUs and concurrency 16, increasing the reference cache capacity from 256 to 1024 entries improved throughput by 32.0% and reduced mean latency by 24.3%. The memory cost is small because the encoded code tensors are compact. The larger cache mainly prevents the active speaker working set from being evicted.
AR Engine
The MOSS AR engine has two layers of computation: the Qwen3 backbone and the local transformer frame-decode loop. SGLang-Omni captures both with CUDA Graphs but keeps them separate because their structures and ownership are different.

Eager vs. CUDA Graph execution
The backbone graph uses SGLang’s standard CUDA Graph path for causal LM decoding. The MOSS-specific frame graph captures a complete local transformer micro-loop for one frame: stop/continue sampling, 12 sequential codebook projections, codebook feedback, and feedback embedding assembly for the next frame. This removes launch overhead from a very small but highly serial loop.
To enable graph replay, MOSS stores per-request decode state in a persistent GPU-side pool. Feedback embeddings, sampling parameters, seeds, counters, and audio history retain stable addresses across frames. SGLang-Omni also moves the generated-row radix hash to the GPU, avoiding per-frame CPU hashing and D2H synchronization.
The 13 sampling operations for each frame use a seeded GPU sampler. We compile only this sampling path, not the backbone or local transformer. On SeedTTS English with concurrency 16, this narrow optimization improved throughput by 12.3%, reduced mean latency by 11.1%, and reduced mean RTF by 10.5%, without changing the execution path of the larger model.
Streaming Vocoder
The vocoder stage converts generated RVQ frames into audio chunks. Because MOSS-Audio-Tokenizer-v2 supports stateful streaming decode, SGLang-Omni retains a persistent codec streaming session inside the vocoder executor.
The scheduler manages stream slots, an offline fallback slot, chunk thresholds, and coalesced decode steps. The first chunk can use a smaller threshold to reduce time to first audio, while subsequent chunks use a larger window to improve throughput. When multiple requests have enough pending frames, the scheduler combines them into a single codec call for decoding.
Short streaming chunks are highly sensitive to launch overhead, so SGLang-Omni uses CUDA Graphs to capture common vocoder frame counts. In the implementation, codec state buffers retain stable addresses and are updated in place, allowing the graph to be replayed across streaming steps.
The acceleration is most significant for short streaming chunks:
| Frames per Step | Eager | CUDA Graph | Speedup |
|---|---|---|---|
| 4 | 66.3 ms | 30.1 ms | 2.20x |
| 5 | 65.8 ms | 30.7 ms | 2.14x |
| 8 | 65.6 ms | 34.0 ms | 1.93x |
| 13 | 65.4 ms | 40.4 ms | 1.62x |
| 25 | 74.8 ms | 58.3 ms | 1.28x |
| 100 | 222.9 ms | 215.3 ms | 1.04x |
When the frame count has not been captured or memory is constrained, the graph path falls back to eager decoding. Streaming/non-streaming consistency checks cover this path.
Memory Budgeting
In the default MOSS Local configuration, preprocessing, AR generation, and vocoder execution can be colocated on a single GPU. This compact layout is convenient, but the AR engine and codec runtime have different allocation patterns. SGLang-Omni therefore gives the AR engine an explicit colocated memory contract and reserves headroom for codec runtime allocations and streaming state.
With a single-GPU colocated configuration and concurrency 8, explicit codec memory budgeting improved throughput by 8.9% and reduced mean RTF by 8.4%. More importantly, it makes deployment behavior under memory pressure predictable.
Performance
We evaluated the optimized serving path on the SeedTTS English set containing 1088 samples. The results below come from a complete CI evaluation with vocoder CUDA Graph enabled, using 2x GPUs and client concurrency 16. ASR scoring used Qwen3-ASR-1.7B, and speaker similarity used a WavLM-Large fine-tune.
| Mode | Completed / Failed | Throughput | Audio Throughput | Mean Latency | Mean RTF | WER |
|---|---|---|---|---|---|---|
| Non-streaming | 1088 / 0 | 5.976 req/s | 26.303 audio s/s | 2.669 s | 0.644 | 1.75% |
| Streaming | 1088 / 0 | 2.909 req/s | 12.804 audio s/s | 5.474 s | 1.322 | 2.14% |
Non-streaming reached 5.976 req/s, with a mean RTF of 0.644. Streaming emits incremental audio chunks. At concurrency 16, the average inter-chunk interval was 0.109 s, and each request emitted an average of 8.82 chunks. Lower streaming throughput is expected: the vocoder runs more frequently with smaller chunks and shares GPU time with the AR engine.
The quality metrics for the two modes remained close. In the same CI run, non-streaming WER was 1.75%, while streaming WER was 2.14%. The streaming/non-streaming artifact consistency checks also passed.
Do not add the measurements from individual optimizations together into a single headline number, because they were collected under different hardware and concurrency settings. They are better understood as a breakdown of MOSS’s time distribution: reference caching removes redundant encoder work, frame CUDA Graphs remove local-loop launch overhead, sampler compilation optimizes the hot sampling path, vocoder CUDA Graphs accelerate short streaming chunks, and memory budgeting stabilizes colocated deployment.
Try It Yourself
The SGLang-Omni MOSS-TTS-Local cookbook provides complete setup instructions, API options, and streaming examples. The minimal path is as follows:
Install and Start the Service
docker pull lmsysorg/sglang-omni:dev
docker run -it --gpus all --shm-size 32g --ipc host --network host --privileged \
 lmsysorg/sglang-omni:dev /bin/zsh

git clone git@github.com:sgl-project/sglang-omni.git
cd sglang-omni
uv venv .venv -p 3.12
source .venv/bin/activate
uv pip install -v -e .

hf download OpenMOSS-Team/MOSS-TTS-Local-Transformer-v1.5

sgl-omni serve \
 --model-path OpenMOSS-Team/MOSS-TTS-Local-Transformer-v1.5 \
 --port 8000
The default layout colocates the AR backbone and codec/vocoder on a single GPU. Explicit configuration is located at examples/configs/moss_tts_local.yaml.
After the server starts, a basic synthesis request returns a WAV file:
curl -X POST http://localhost:8000/v1/audio/speech \
 -H "Content-Type: application/json" \
 -d '{"input": "SGLang-Omni is a great project for high-fidelity speech generation."}' \
 --output output.wav
See the cookbook for voice cloning, streaming PCM, duration control, pause markup, pronunciation hints, language hints, sampling parameters, and benchmark commands.
Roadmap
The current pipeline is fully usable end to end, but several areas are still worth improving:
Pool-native frame CUDA Graph. The current frame-decode graph uses persistent state pools, but some staging remains around the sampling parameters and generated rows. A more native pool-to-pool graph path could simplify the launch/resolve boundary.
Adaptive streaming scheduling. Streaming TTS involves a real latency-throughput trade-off. We are exploring load-aware chunk sizing, priority-aware slot scheduling, and improved coalescing policies so that low-load requests receive their first audio more quickly while high-load deployments recover more throughput.
Broader compilation coverage. The codec encoder and Qwen3 backbone still offer room for targeted compilation experiments. We will keep the compilation scope sufficiently narrow to avoid cold-start regressions and output changes.
Wider benchmark coverage. Current measurements focus on SeedTTS English in CI. We plan to expand them to Chinese, multilingual evaluation, long-form generation, multiple speaker pools, different reference lengths, and traffic mixes that more closely resemble production.
Join Us
If you are interested in TTS, omni models, streaming inference, CUDA Graphs, scheduling, communication, model onboarding, benchmarking, or production serving, we welcome you to join us.
Acknowledgements
SGLang-Omni - Jiaxin Deng, Haoguang Cai, Shangming Cai, Yuhao Chen, Kangxiang Shao, Hao Jin, Yifei Gao, Jingwen Gu, Zhihao Guo, Chenchen Hong, Xinli Jing, Xiangrui Ke, Estella Liu, Xinyu Lu, Ratish Palanisamy, Mick Qian, Yijiang Tian, Zijie Xia, Xuesong Ye, Yue Yin, Gaokai Zhang, Xiaoyu Zhang, Chenyang Zhao, Yichi Zhang.
MOSS-TTS Local Transformer v1.5 - Yitian Gong, Kuangwei Chen, Zhicheng Zhang, Botian Jiang, Yiyang Zhang, Kang Yu, Yang Gao, Xiaogui Yang, Qinyuan Chen, Zhaoye Fei, Shimin Li, Xipeng Qiu.
Learn More
- Model: OpenMOSS-Team/MOSS-TTS-Local-Transformer-v1.5
- Serving framework: SGLang-Omni on GitHub
- Documentation: SGLang-Omni docs
- MOSS-TTS-Local cookbook: MOSS-TTS-Local in SGLang-Omni
- MOSS optimization roadmap: MOSS TTS Performance Optimization Roadmap (#637)
- Design background: SGLang-Omni: Redesigning the Inference Framework for Multi-Stage Generative Models